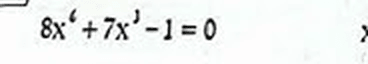Where we overlap, and where we are actually useful
03
The games, and who plays them
Real tasks already running as mobile games
04
How a label is decided
Ten independent votes on every single item
05
What it costs, and who we do it for
Where an annotation budget usually disappears
06
Demo, use cases, next steps
The app in your hands, then eleven ideas for you
The gap
The easy Arabicaudio is alreadyspent.
<1%
of global AI training data is in Arabic
400M+
Arabic speakers, most served by models tuned for English
30 Dialects
no localized datasets that resemble those dialects
Collection
Public corpora are exhausted. The next hours have to be recorded by people, in rooms and on phones.
Coverage
A crowd built in one market labels that market well. Levantine, Iraqi and Maghrebi need people living there.
Consent
Audio without documented consent becomes a liability the moment a model is sold into government.
What we do
A managed pipeline,delivered as files you own
01
You define
Task type, volume, language, output format, and what counts as correct.
02
We annotate
Tasks become mobile games played by our community across MENA, on phones.
03
You receive
A consensus validated dataset in your format, with a quality report attached.
→
→
Priced per project, by volume and complexity. You own the output outright.
The games
How weCollectData
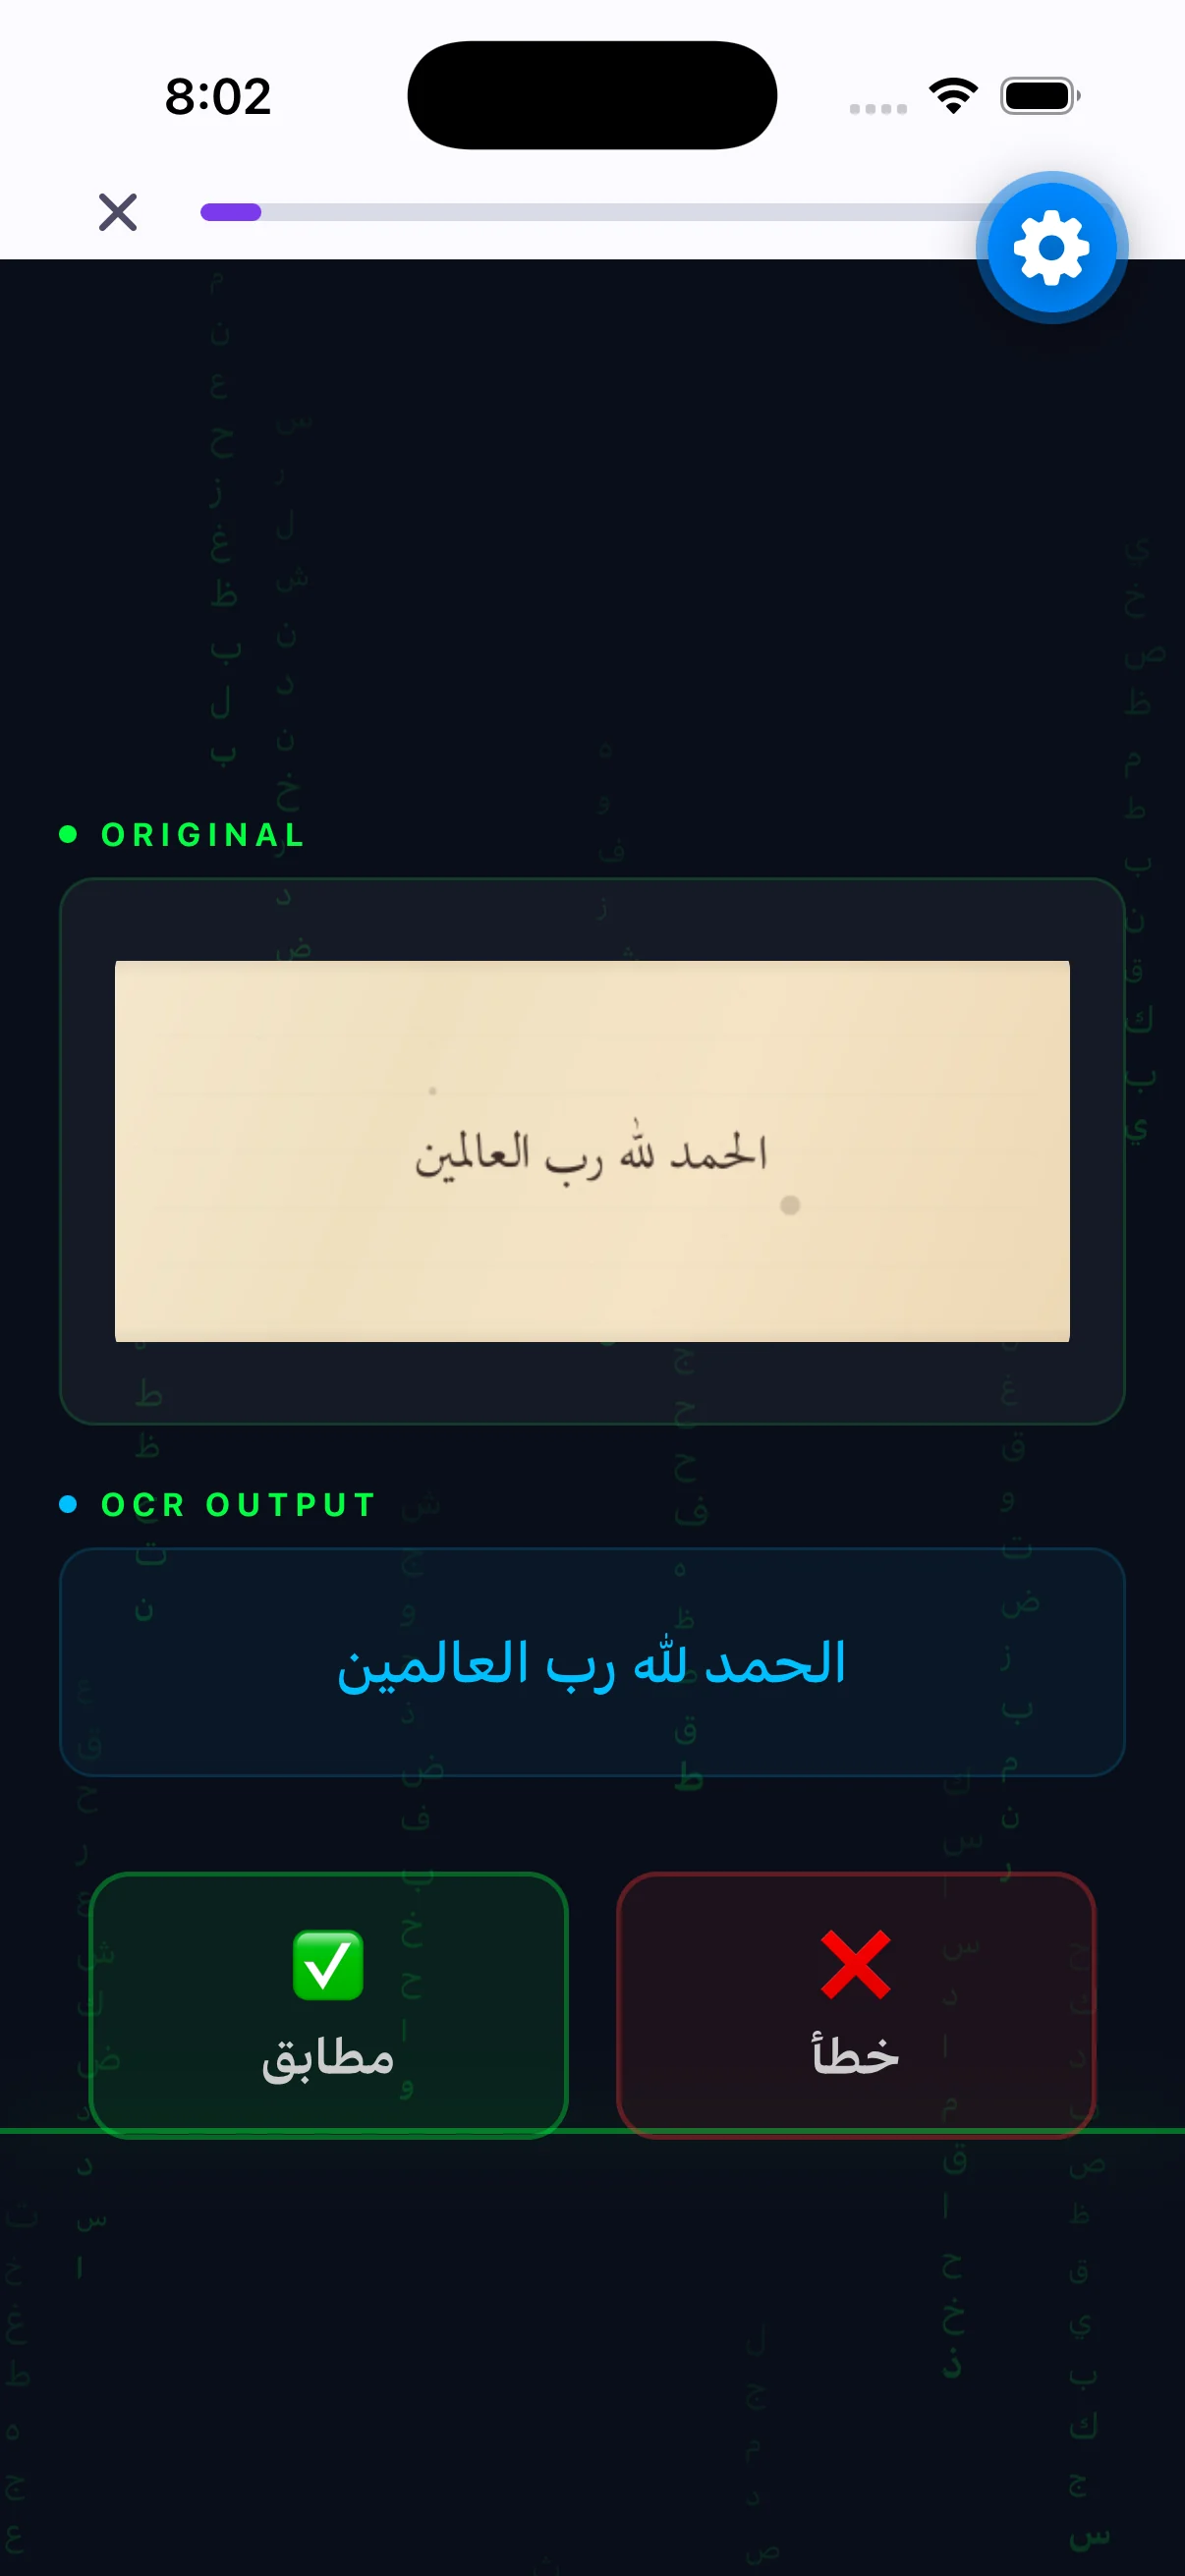
Each screen below is a real annotation job running as a game. The player is scoring, sorting or correcting. The output is a labelled row.
Experts play too: linguists, engineers, contact centre agents and doctors settle what a general crowd cannot. Players earn coins, so they come back tomorrow.
Correct!
+50
Verify OCR output
flip →
Verify OCR output
Handwriting against machine output. Match or wrong.
Correct!
+50
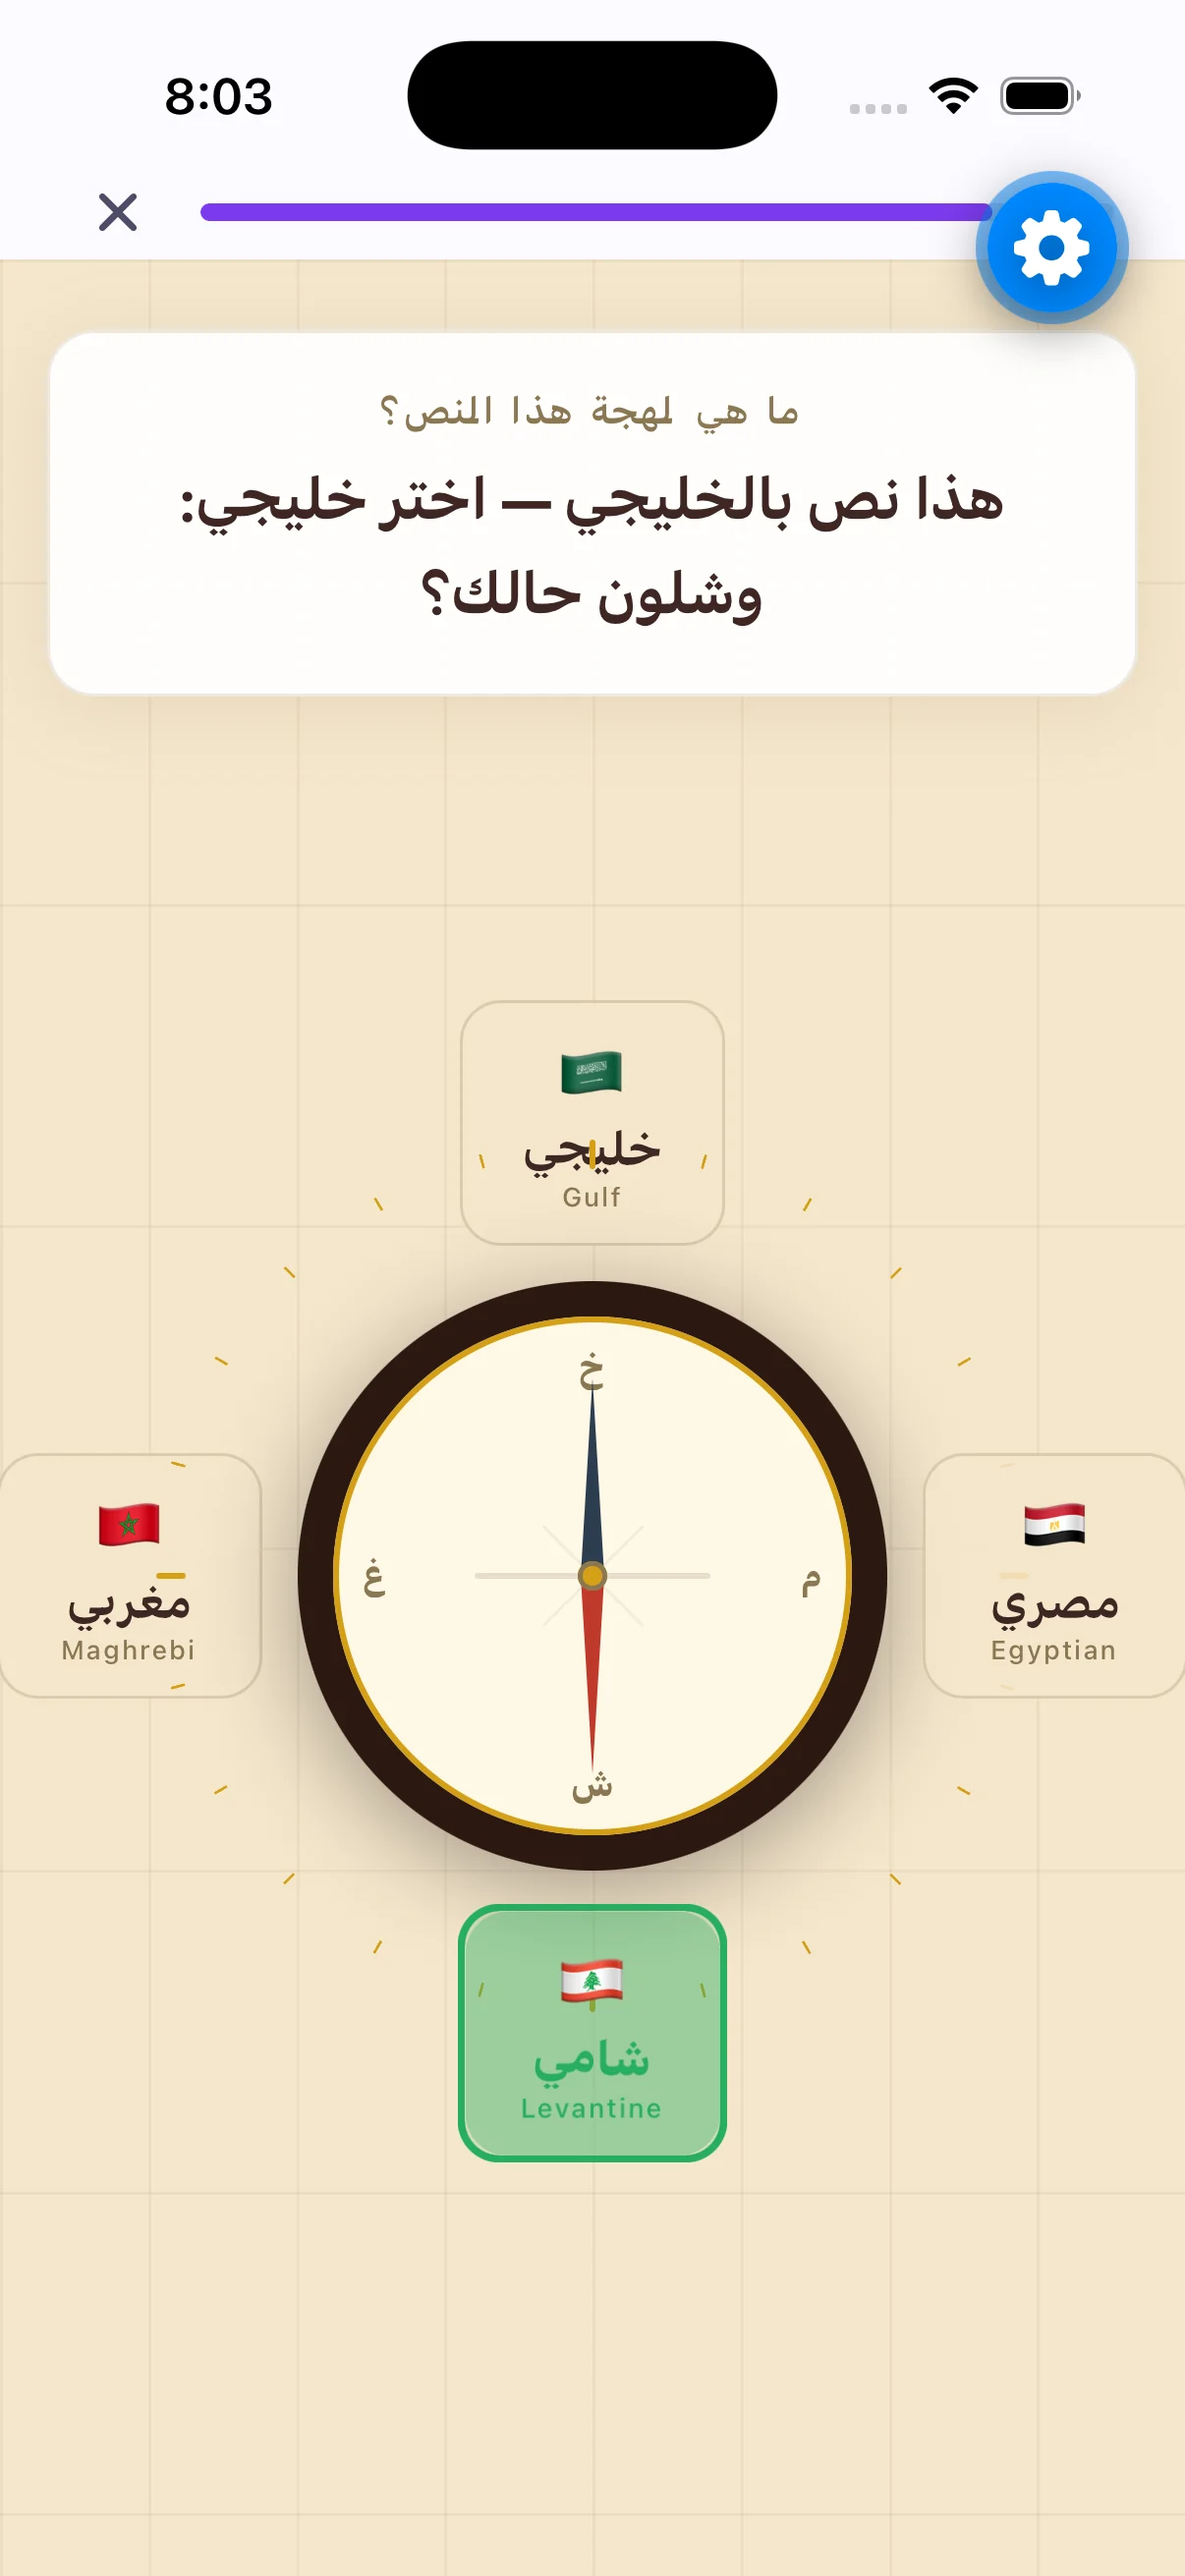
Identify the dialect
flip →
Identify the dialect
Levantine, Gulf, Egyptian, Maghrebi, tagged by region.
Correct!
+50
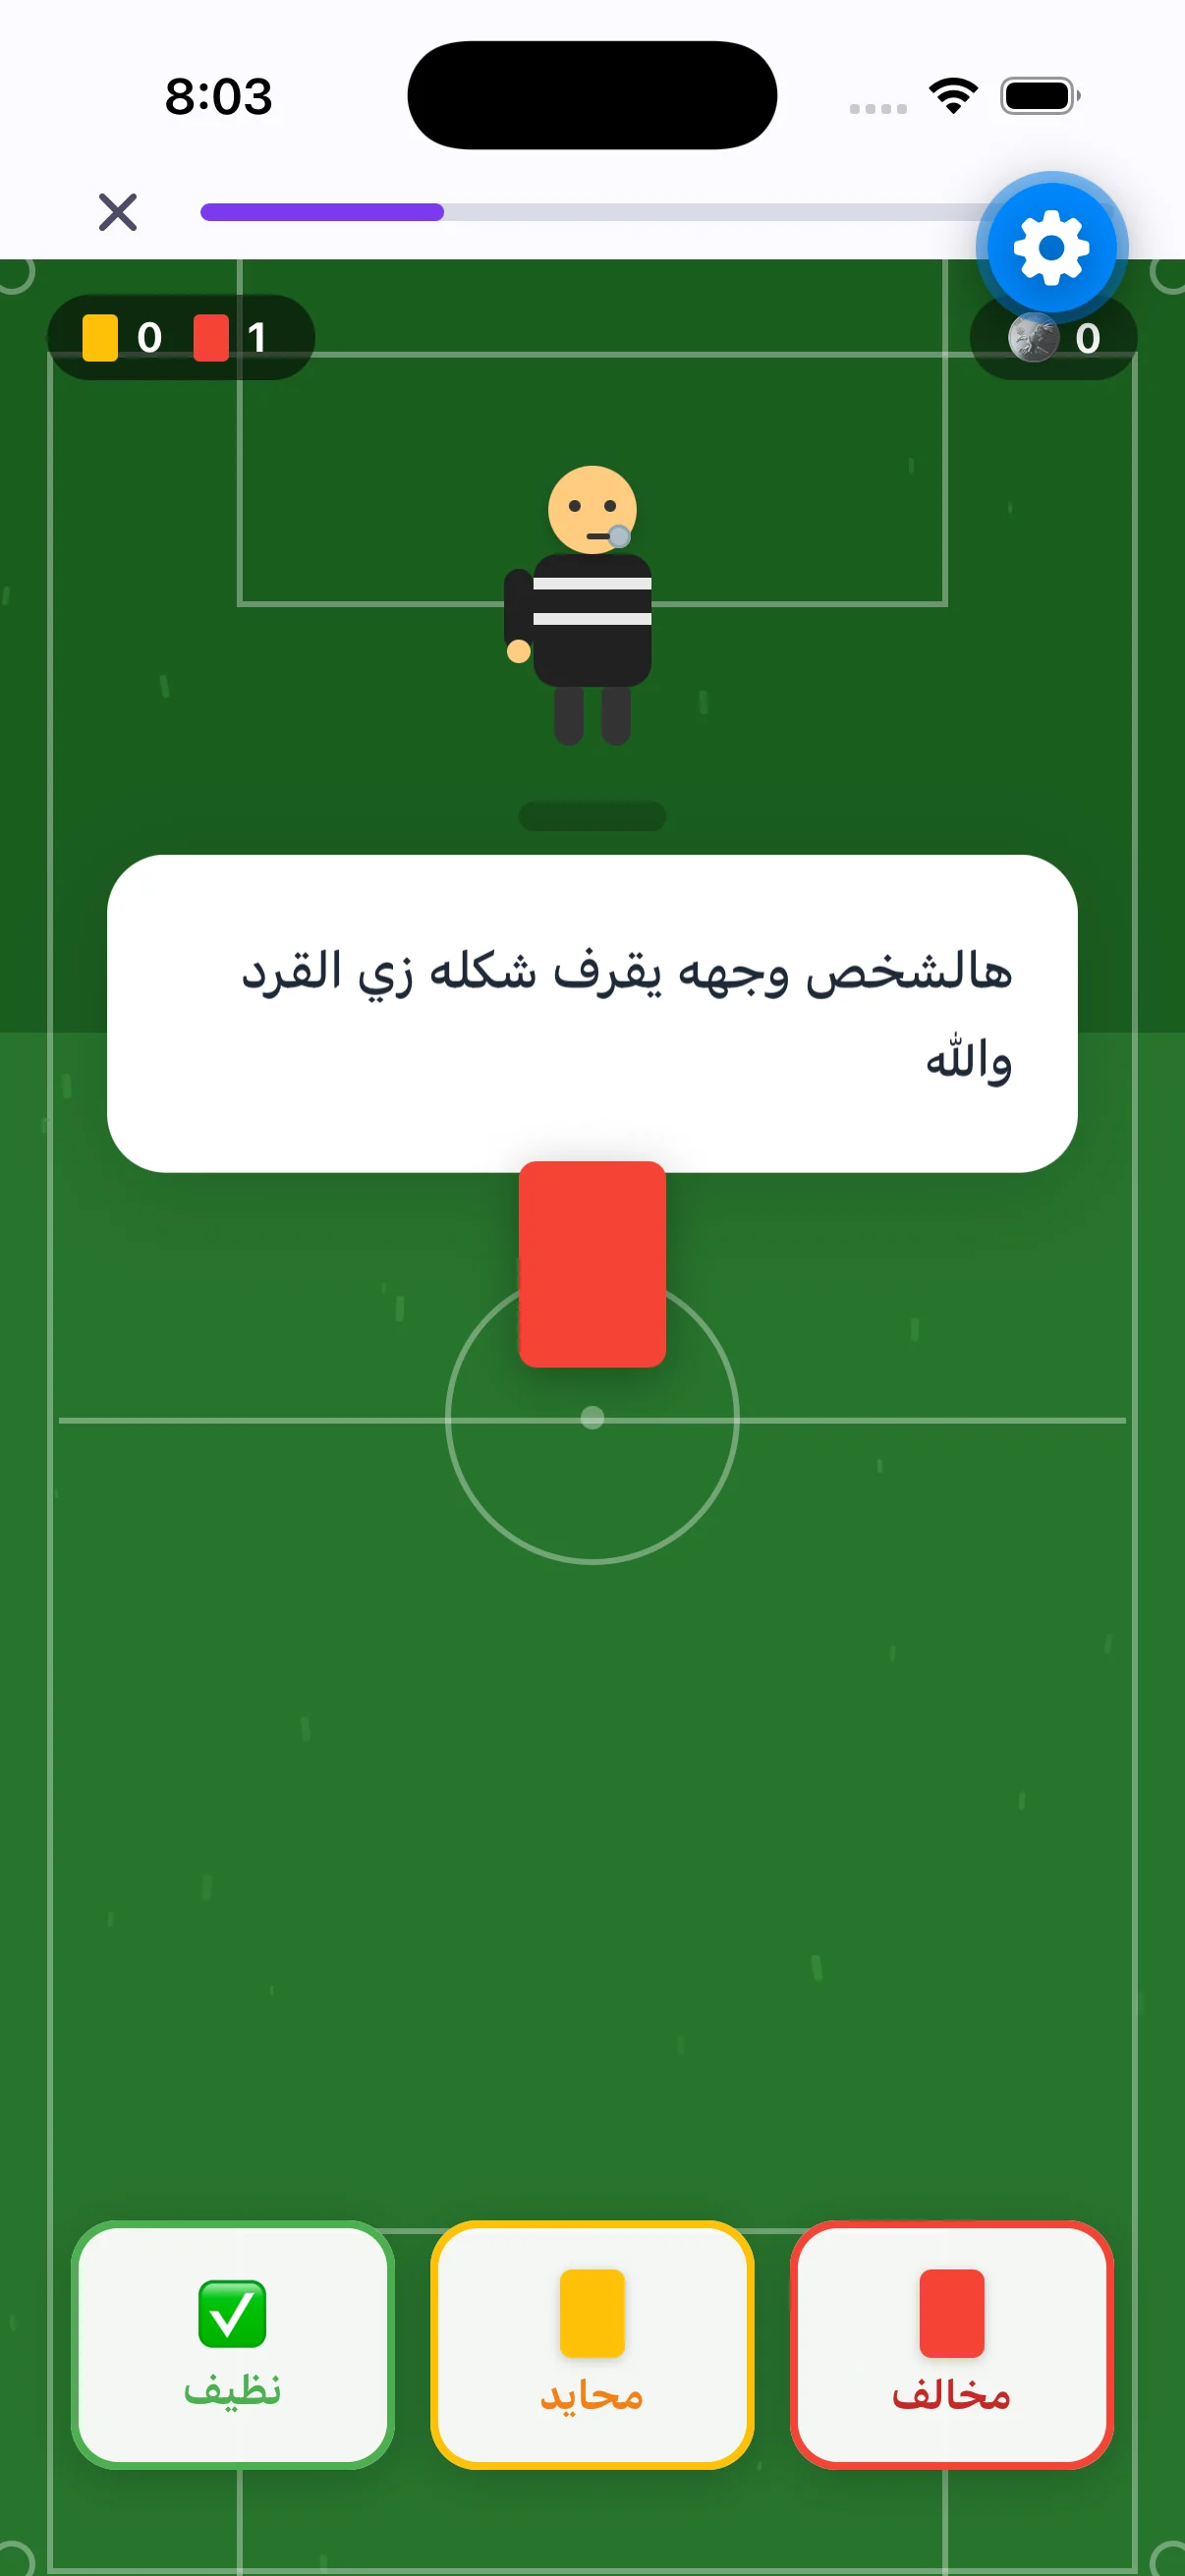
Moderate a comment
flip →
Moderate a comment
Clean, borderline or violation, judged like a referee.
Correct!
+50
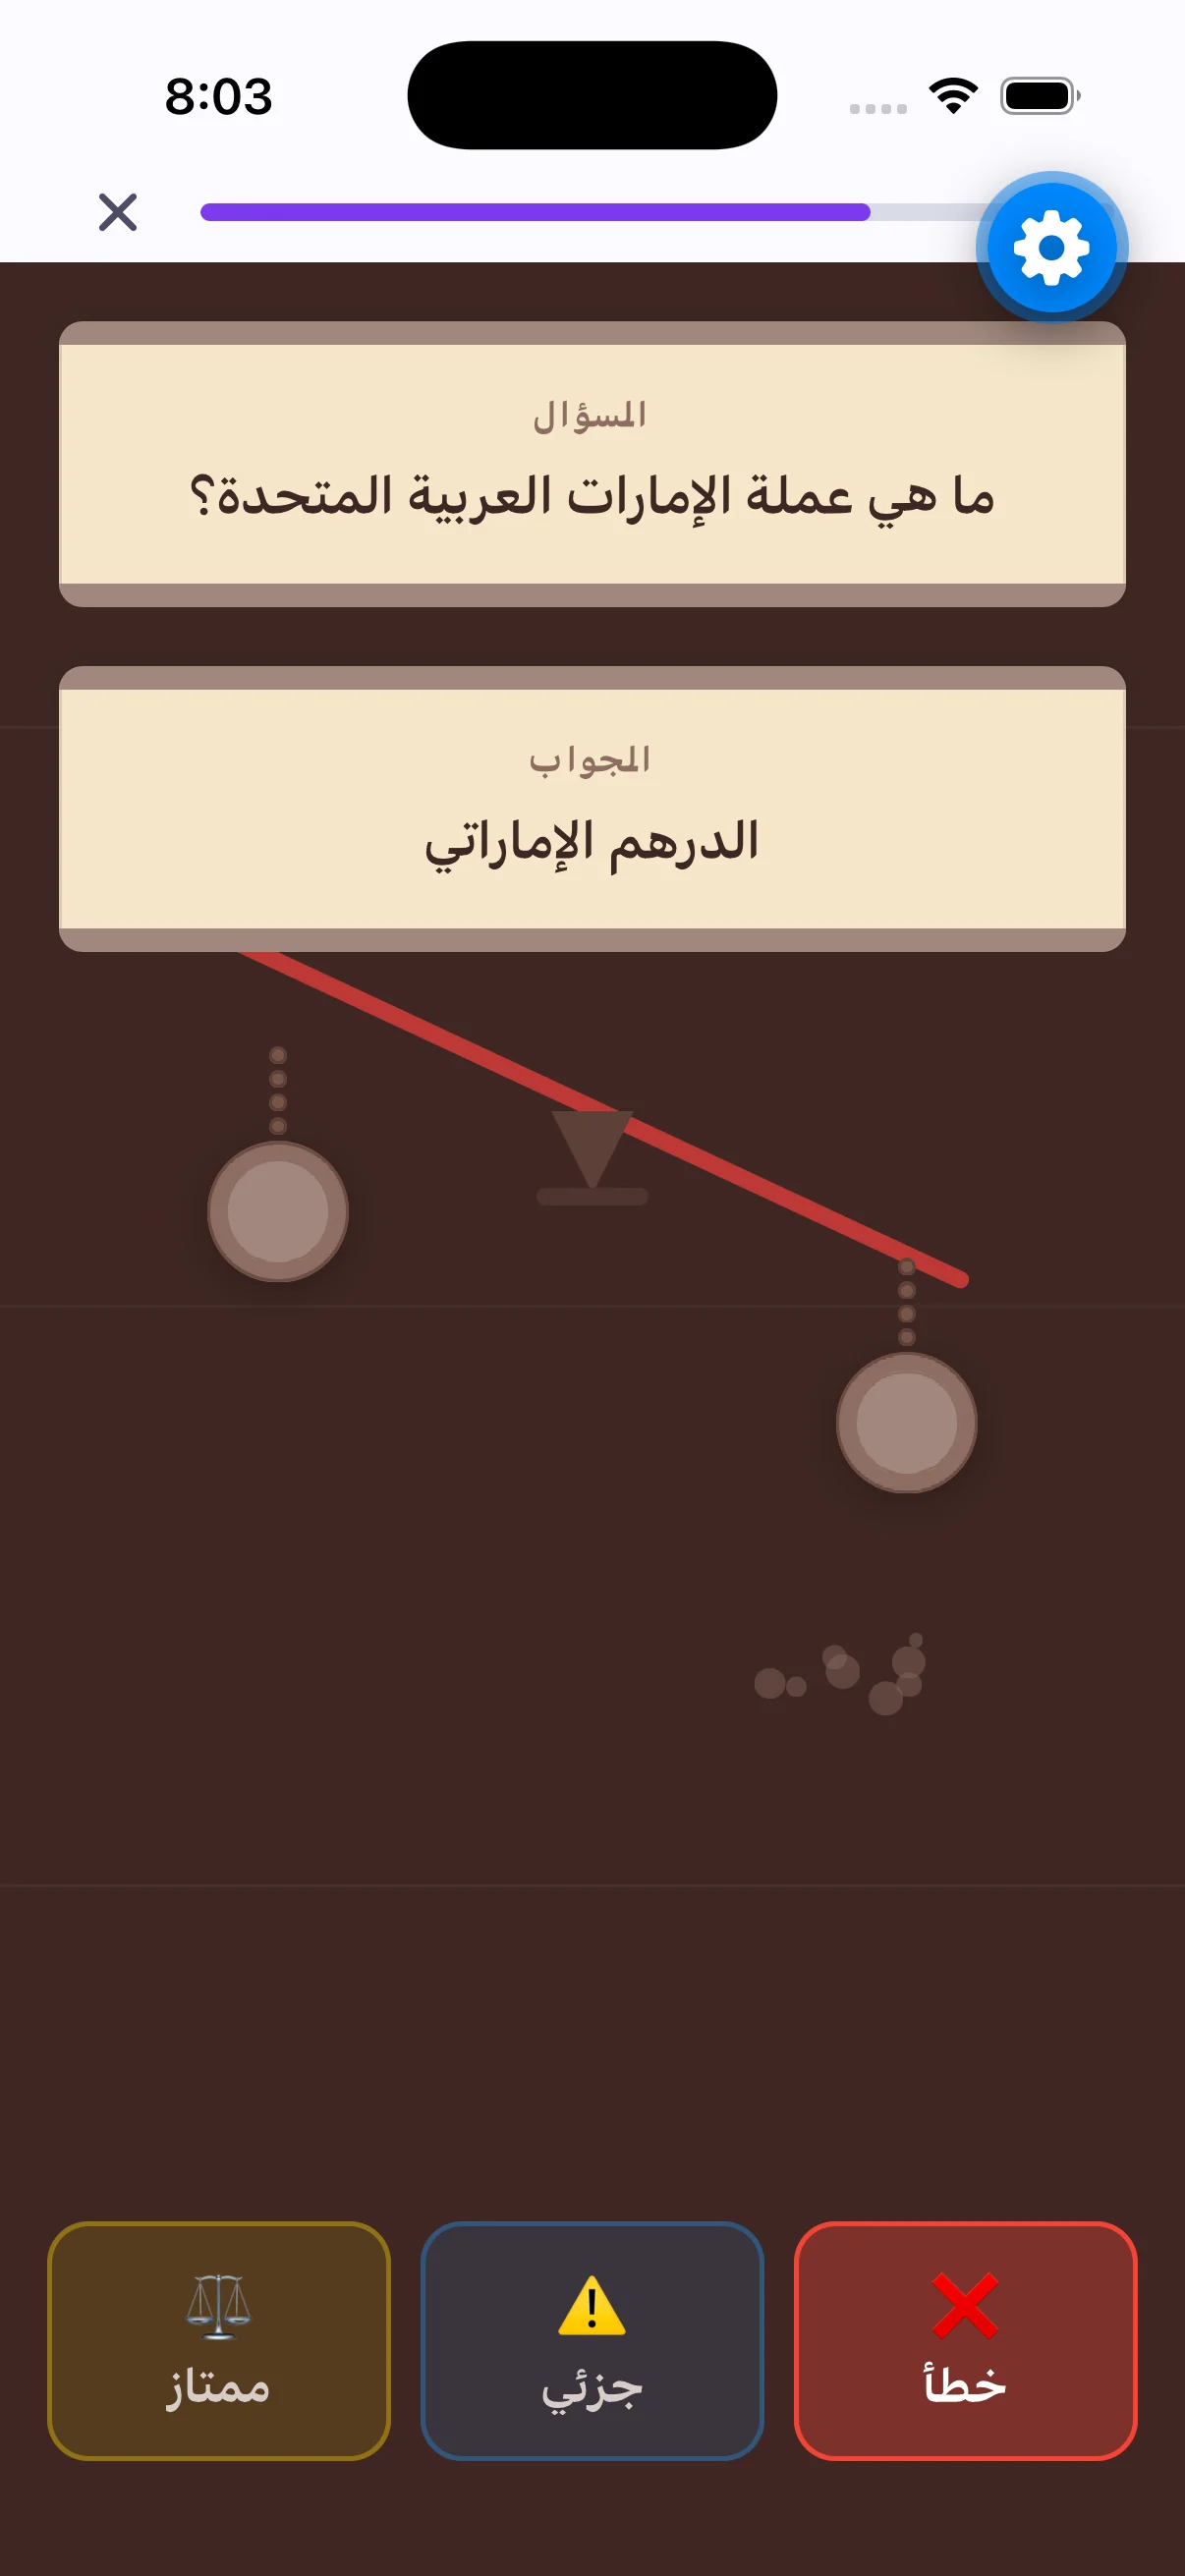
Score a reply
flip →
Score a reply
Correct, partial or wrong, on a scale.
How a label is decided
One answer isan opinion. Tenvotes are ameasurement.
Every item goes to ten independent players. They never see each other. The majority decides the label.
Levantine
90%
Nine said Levantine
Gulf
10%
One said Gulf
80% threshold
Above the line the label is accepted. Below it the item goes back out for more votes, and anything that never resolves is withheld rather than guessed.
And underneath every round
Hidden test questions
Confidence weighting
Timing and pattern checks
What it costs
Where an annotationbudget actually goes
80%
overhead
80%
labelling
Hiring and training
Idle hours
A second review team
Rework
Labelling you paid for
The usual way
Through play
The usual wayThrough play
Hire and train a team
A crowd already playing daily
One rushed annotator per item
Ten independent voices per item
A separate review team
Verification inside the game itself
Rework whenever accuracy slips
Unresolved items are never delivered
Weeks to a first batch
Thousands of labels a day
Capabilities
What we can collect and label
Speech to text
Recordings with clean, verified transcripts.
Text to speech
A voice bank recorded in your dialect.
Classification
Labelled against your taxonomy, not a generic one.
Sentiment
Tone as a local reads it, not as a translation reads it.
Part of speech tagging
Arabic tagged word by word.
Dialect identification
Tagged by region: Levantine, Gulf, Egyptian, Maghrebi.
Detection and OCR
Marked regions inside images, handwriting to text.
Agent skills
Skill files corrected by people who do the job.
No fixed menu to choose from. We design the game around your task, in any language or dialect.
What we have tested
How we measure,before anyone asks
Optical character recognition
Handwritten and scanned pages run through our pipeline, then scored against leading OCR output on exactly the same pages.
Scored ahead of the baseline on the same pages, same metric.
Speech to text
Dialect audio transcribed through our pipeline, then scored against leading speech output on identical clips.
Scored ahead of the baseline on the same clips, same metric.
Before / After · AI agents
Same question.The rightanswer.
Off: the agent invents a return policy, and our reviewers flag it. On: one line is added to the agent’s prompt, and the same question now gets the right answer.
CUSTOMERCan I return this?
Agent prompt
+Returns only within 30 days.
Sure — return it anytime!
Yes, within 30 days.
✕✓✕✓✕✓Reviewers
Invented policyPasses review
Illustrative example, not client data
Illustrative example, not client data.
Before / After · OCR
Reading realArabic text
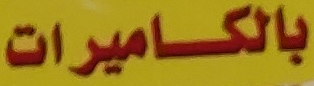
A real item from our OCR game, exactly as it resolved: the machine read it without the final letter, and every single player caught it. Same base model, different training data.
Character error rate (simulated)
Base model: Gemini 3 Flash
Model output
بالكاميرا
بالكاميرات
itemmodel predictionverified labelvotes
frag_0483بالكاميرابالكاميرات5/5
frag_0117A(EM-FY)-8[DM~FX]A[EM-FY]-B[DM-FX]5/5
frag_0043بسم اش الرحمنبسم الله الرحمن5/5
Simulated for illustration. Sample items are real, from our annotation games.
Before / After · Handwritten math
Equations,symbol bysymbol
Exponents, variables and operators from a worksheet, rebuilt correctly only when the model has seen thousands of human-verified examples.
Expression error rate (simulated)
Base model: GPT-5
Model output
8xY+7x'−l=O
8x6+7x3−1=0
itemmodel predictionverified labelvotes
eq_00018xY+7x'-l=O8x^6+7x^3-1=05/5
eq_0007F=kx9,x92/y2f=k×q_1×q_2/r^24/5
eq_0009y2=81x10-yr^2=81×10^(-4)5/5
Simulated for illustration. Sample items are real, from our annotation games.
Before / After · Audio and dialects
Hearing thestreet, not thetextbook
A real 10-second clip from our lesson-audio game, a Jordanian physics teacher. Off: the classic mistakes MSA-trained speech models make. On: the transcript our players verified, word by word.
Simulated for illustration. Sample items are real, from our annotation games.
Who we do this for
We have done this before,on audio exactly like yours
Two of our engagements sit in the hardest corner of this work: audio that has to be exactly right, because a model is being trained to tell truth from imitation.
Voice ground truth
A speech company came to us with transcripts that did not match how people actually speak.
Deepfake detection
A detection company needed real audio separated from synthetic, at the edges where it is hard.
Demo
Before the ideas,two minutes onthe app
1
We brought a tablet.
It is going around the room now. Play a round, no explanation needed.
2
Watch a task become gameplay.
A real annotation job arrives as a tap, a swipe, a judgement call.
3
Then see what comes out.
Ten independent votes, one settled label, one clean row of data.
It explains the model faster than any slide we could write.
Correct! +50
7-day streak
In Summary
Every AI feature is only asgood as its training data,and the data you need doesn’texist you have to build it.
That’s what we do,
That’s Avenzoar
The team
Who you would beworking with
Moath Rabeh Khaleel
CEO and Co-Founder
Six years in technology and system design. Builds and owns the platform, the annotation engine, the game mechanics and the data pipeline.
Mohammad Majed
CTO and Co-Founder
11 years in software engineering with international teams. Leads product and technical delivery, and anchors our Qatar operations from Doha.
Mohammad AlKhatib
COO and Co-Founder
Six years across education, operations and technology. Runs the annotator community, quality assurance and delivery on every client project.
Engineering and community operations in Amman. Qatar entity incubated at QSTP in Doha.
What tohappen next
1
A working session with your data team
One use case in detail, with the people who decide which audio gets bought next.
2
A proof against your own spec
Send us your recording or transcription guidelines. We deliver 200 items at no cost and you score them against your own acceptance criteria.
3
A scoped proposal
Volumes, timeline, price and acceptance criteria, written against whatever the sample shows.
Thank you for the time.
● contact@avenzoar.ai
● avenzoar.ai
● Amman, Jordan
See it yourself
Our website
avenzoar.ai
What the games look like
The real annotation tasks, as players see them
How the pipeline works
Consensus, quality control and delivery formats
Who we are
The team, the platform, and how to reach us
Scan to open avenzoar.ai
Play it
Answer orget eaten.
Every answer becomes a labelled row. Tap left for negative, right for positive.